You Didn't Write It. You Still Have to Maintain It.
Generated code can be correct and still be expensive to change. I care whether the next engineer can explain its boundaries without reconstructing the prompt.
7 min read
Generated code can be correct and still be expensive to change. I care whether the next engineer can explain its boundaries without reconstructing the prompt.
Micro-frontends and a modular monolith can share strong code boundaries. Their practical difference appears when old and new parts coexist: shell contracts, assets, dependency versions, cross-app state, and rollback need an operating agreement.
Both frameworks can render pages and execute server-side work. A more useful comparison follows one authenticated mutation through cache invalidation, browser state, deployment skew, and the actual hosting path.
Choosing external engineering support is partly about capacity, but the harder questions concern decision ownership, continuity, review authority, and what remains usable after the engagement ends.
Useful observability connects browser intent, API acceptance, durable state, and background outcomes. Sampling, cardinality, missing denominators, privacy, and telemetry failure determine which questions that connection can answer.
Redis can make an application feel dramatically faster, but speed is only useful when ownership, expiration, invalidation, and failure behavior are explicit. Otherwise the cache becomes a second truth nobody can explain.
I arrived at Liberty with a working model for agentic development. Now the company is exploring a more formal approach built around reusable agent skills. I don't know which model will prove better yet, and that uncertainty is the interesting part.
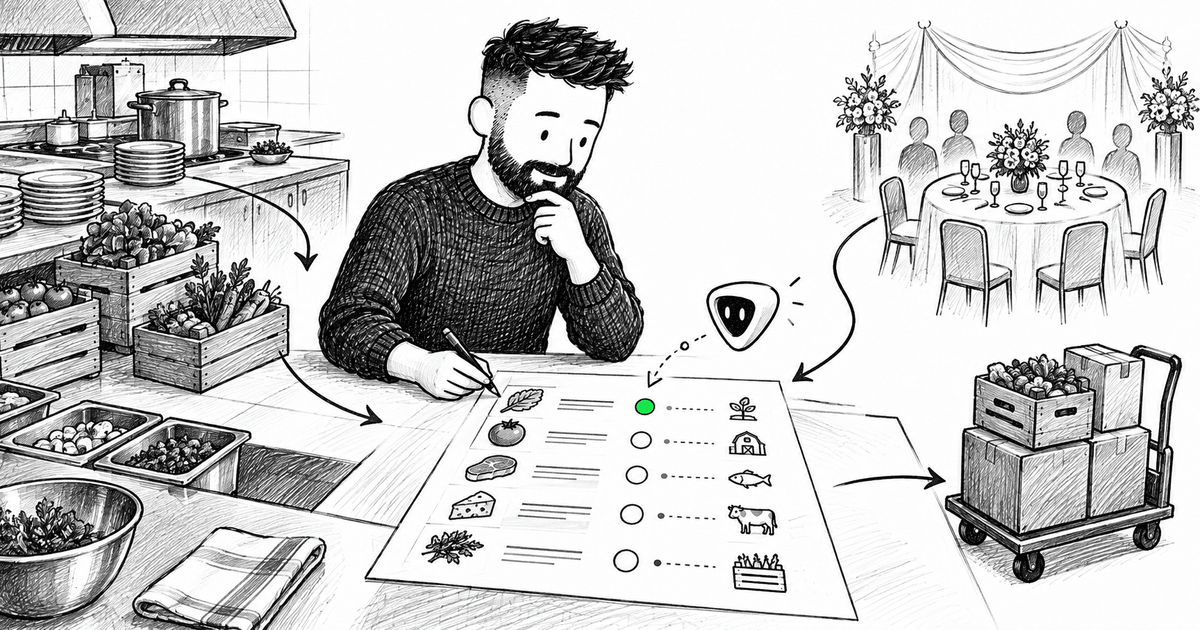
For the Silpo AI Factory hackathon, the interesting problem was not building another AI shopping chat. It was figuring out where AI should stop, where deterministic procurement logic should begin, and how MCP could execute a controlled supplier workflow at the end.
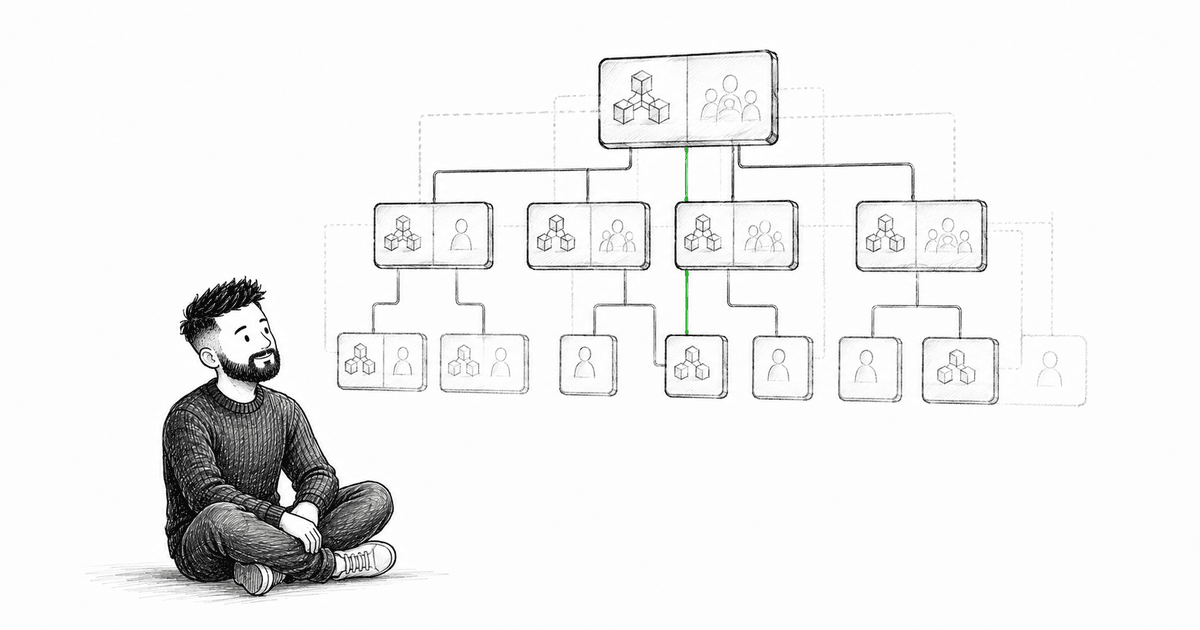
Every micro-frontends pitch I've seen leads with the technical benefits — independent deploys, framework isolation, smaller bundles per team. Almost none of it holds up unless the real problem was organizational to begin with. Conway's Law isn't a fun fact here. It's the actual justification.
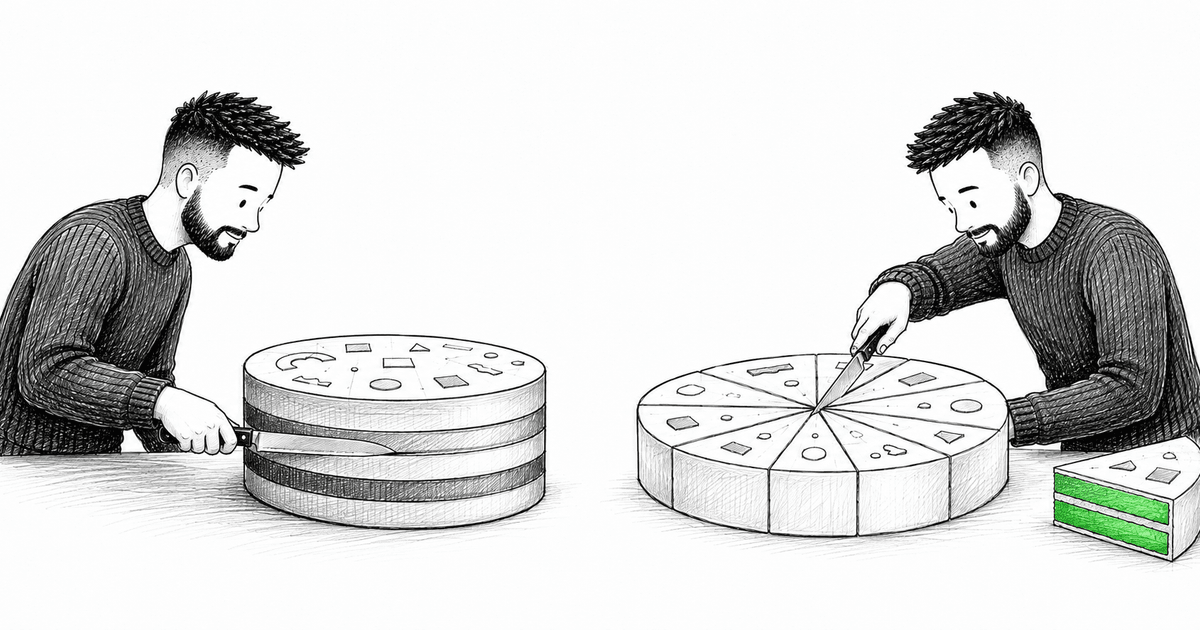
Every frontend architecture is really just a decision about which axis you slice the app along — by technical kind, or by feature. Both are correct. Both eventually hurt. The question worth asking isn't which one is better, it's which one is cheaper to be wrong about later.
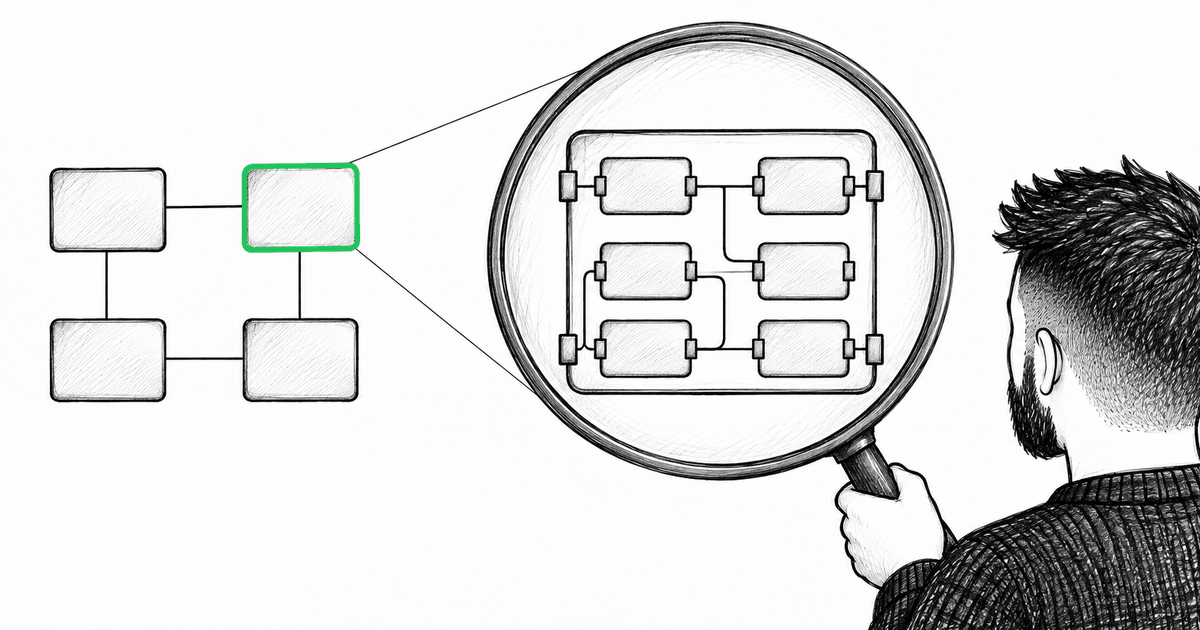
How Nivra went from a vague hackathon direction to a tested WebMCP workspace: choosing the right idea, making architecture the shared context, and proving that human UI, agent tools, and deterministic validation could work from the same model.
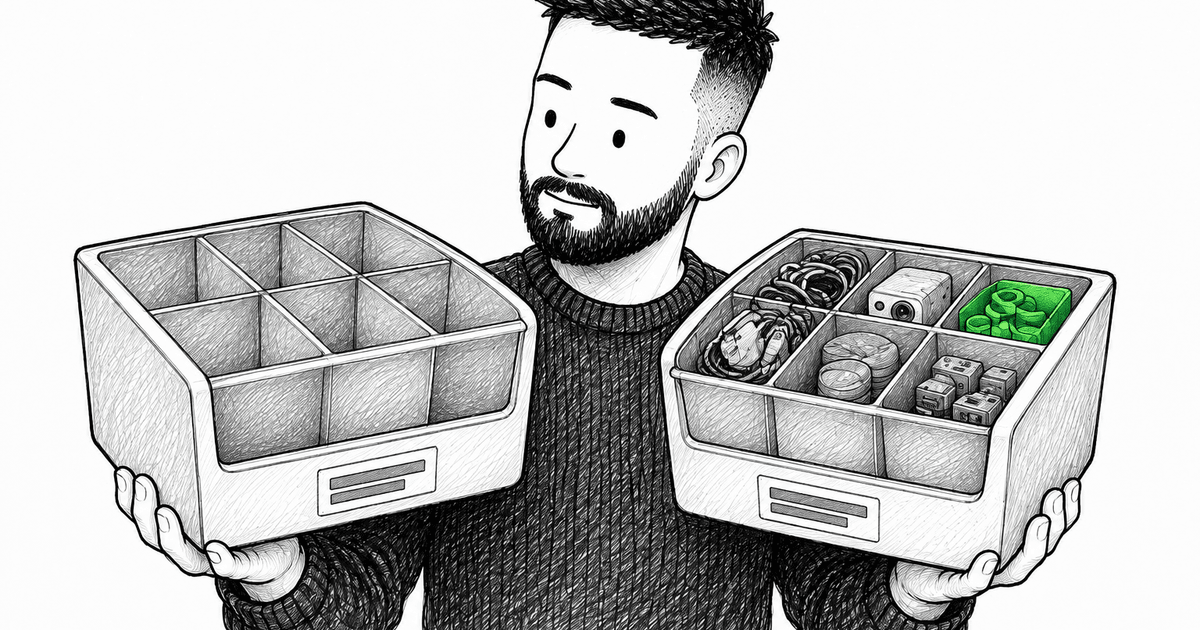
Feature-Sliced Design got popular because frontend spent years being treated as the part of the codebase that didn't need real architecture. It fixed that perception. It did not fix cohesion, and pretending it did is how you end up with a button smeared across ten folders.
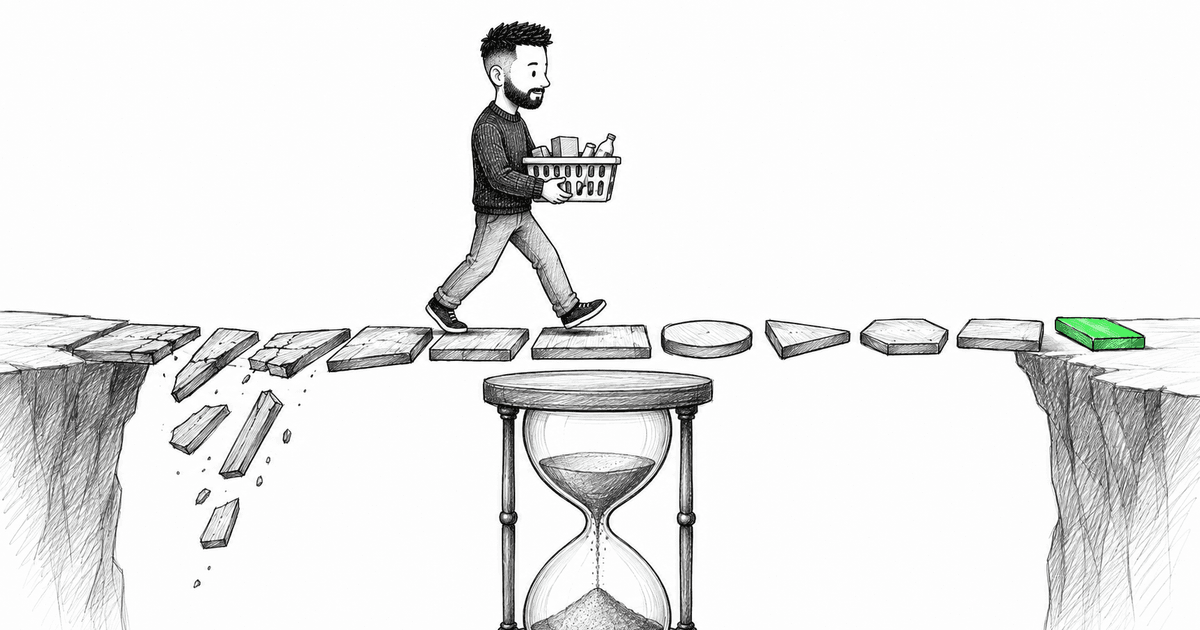
Most of an app can afford to be a little slow, a little clunky, and still get forgiven. Checkout can't. What you're actually selling in that flow isn't a UI — it's time-to-goal. Every architectural choice in there either protects that number or quietly taxes it.
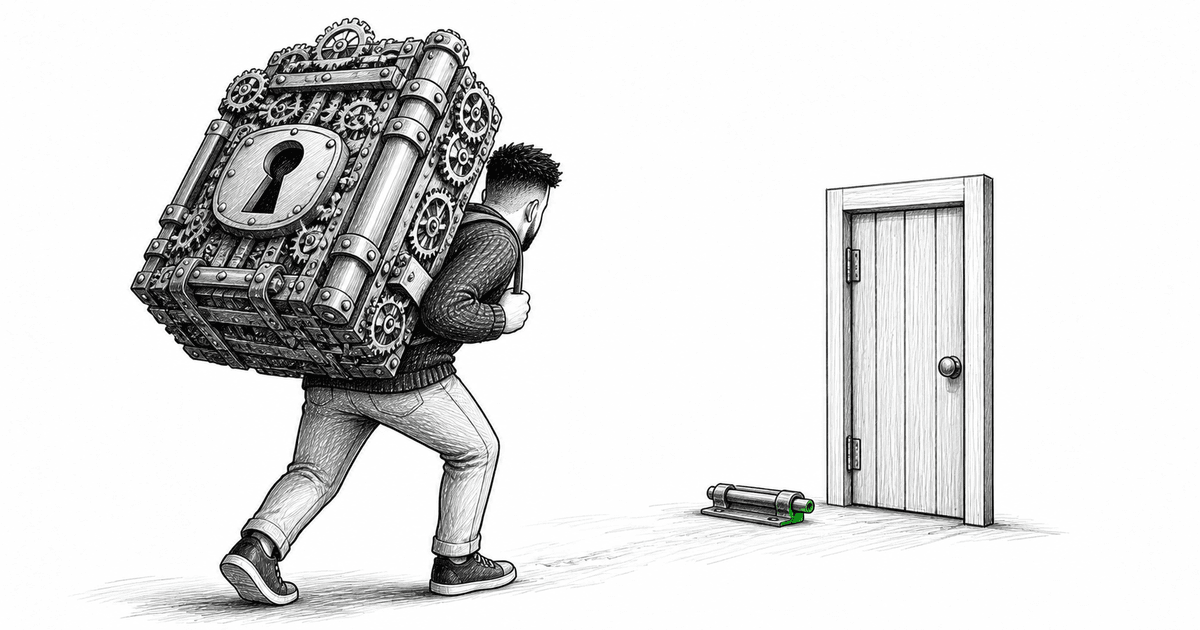
There's a point where a type stops protecting you and starts being a puzzle you have to solve again every time you touch it. I'm not a type wizard and I've stopped trying to be one — because on real React codebases, the complexity that pays for itself is a much shorter list than the internet suggests.
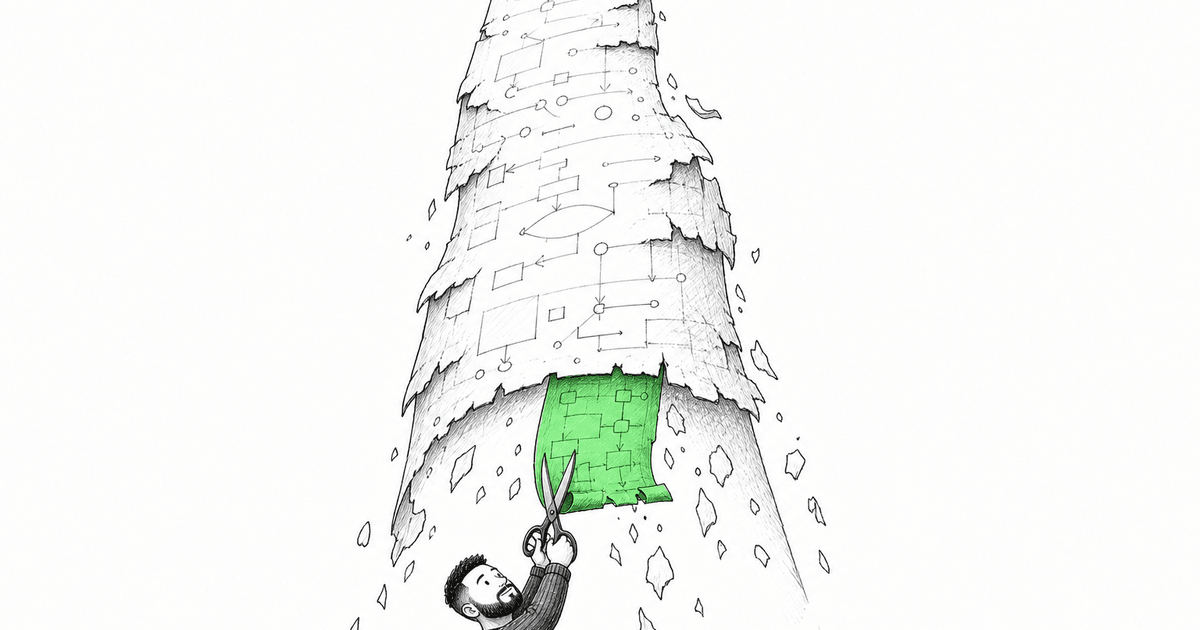
Nobody writes agent rules once and walks away — they write them, then keep adding. A line here after a bad run, a paragraph there after a near-miss. Six months later the file contradicts itself, and the agent is following the version of your project that stopped existing in March.
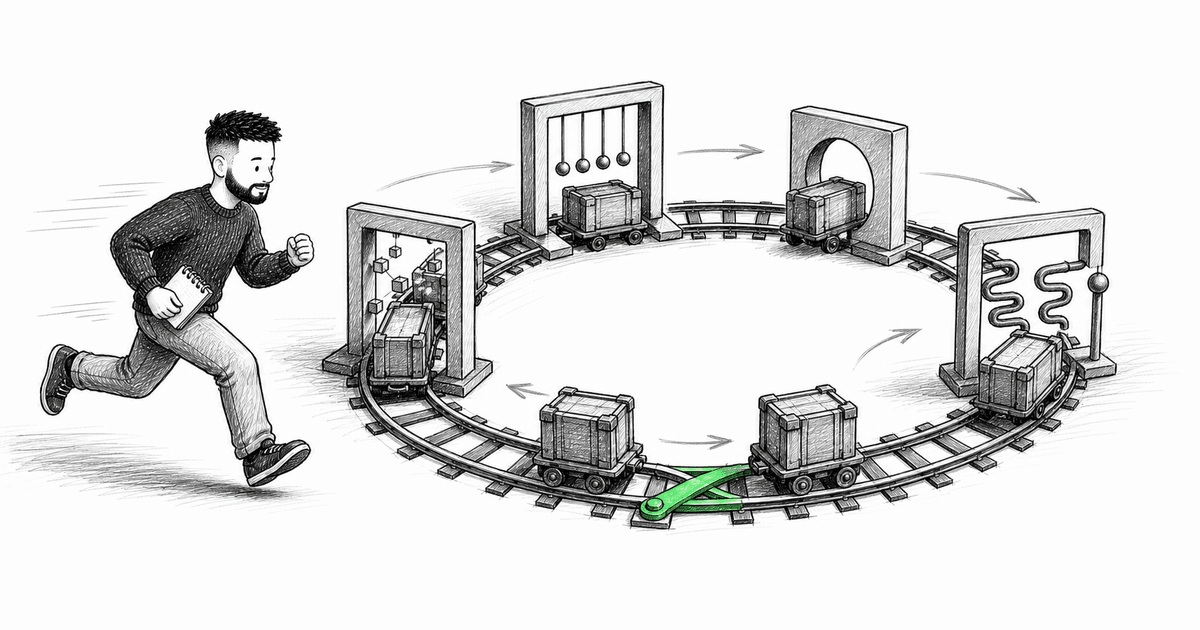
An agent that feels better after a prompt change may still be getting worse. Without a small set of realistic tasks, explicit expectations, and recorded failures, agent improvement is just a sequence of impressions.
A long transcript can remember everything and still help with almost nothing. Durable agent memory is the small set of current facts, decisions, and lessons that makes the next run start from a better baseline.
Autonomy is not a single setting to turn up. A useful agent knows which decisions it owns, which ones it can reverse, and which moments need a human before the next step.
An agent cannot reason about information it cannot reach, and a vague tool description turns a precise capability into a guessing game. Tool design is not plumbing around the model. It is part of how the agent thinks.
A capable model with the wrong context is still a bad agent. The useful part of an agent is not the model in isolation, but the project knowledge, rules, tools, and decisions that shape what it can see before it acts.
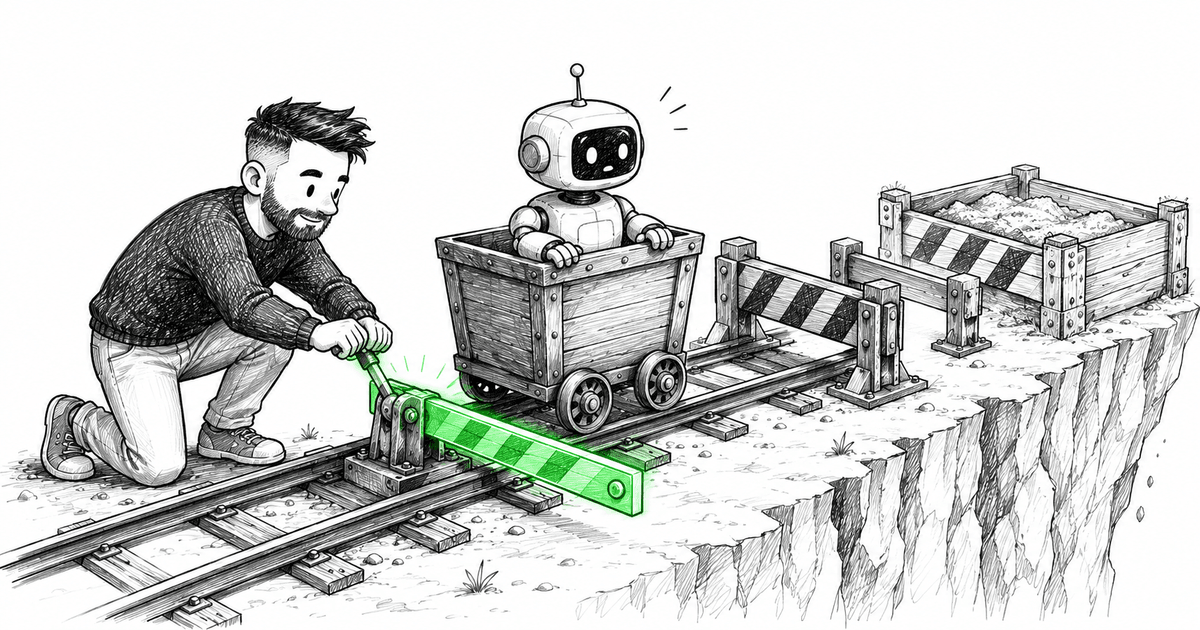
An agent is stateful, and its errors compound: one wrong step sends it down an entirely different path, and it can't tell that it's lost. Autonomy without guardrails isn't trust — it's hoping. The job isn't to make the agent never fail. It's to make sure that when it does, the blast radius is small.
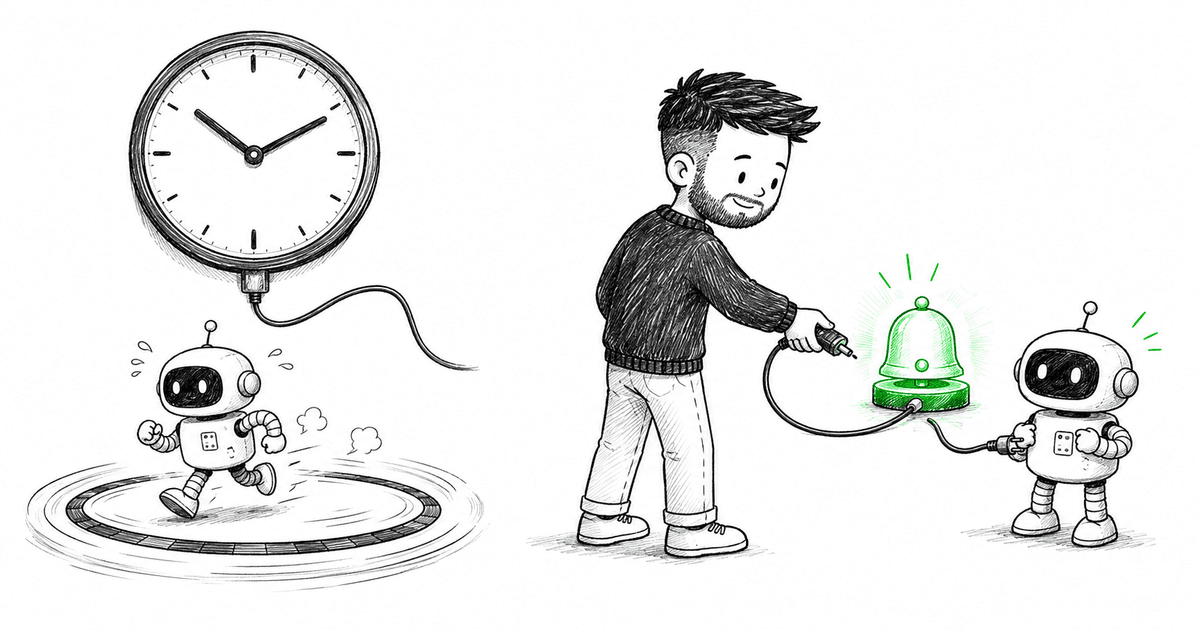
The instinct is to put the agent on a schedule: every few minutes, wake up and check the environment. That instinct is where a lot of runaway costs and pointless runs come from. An agent should be woken by a reason — a commit, a deploy, a failing check — not by a clock ticking over whether or not anything happened.
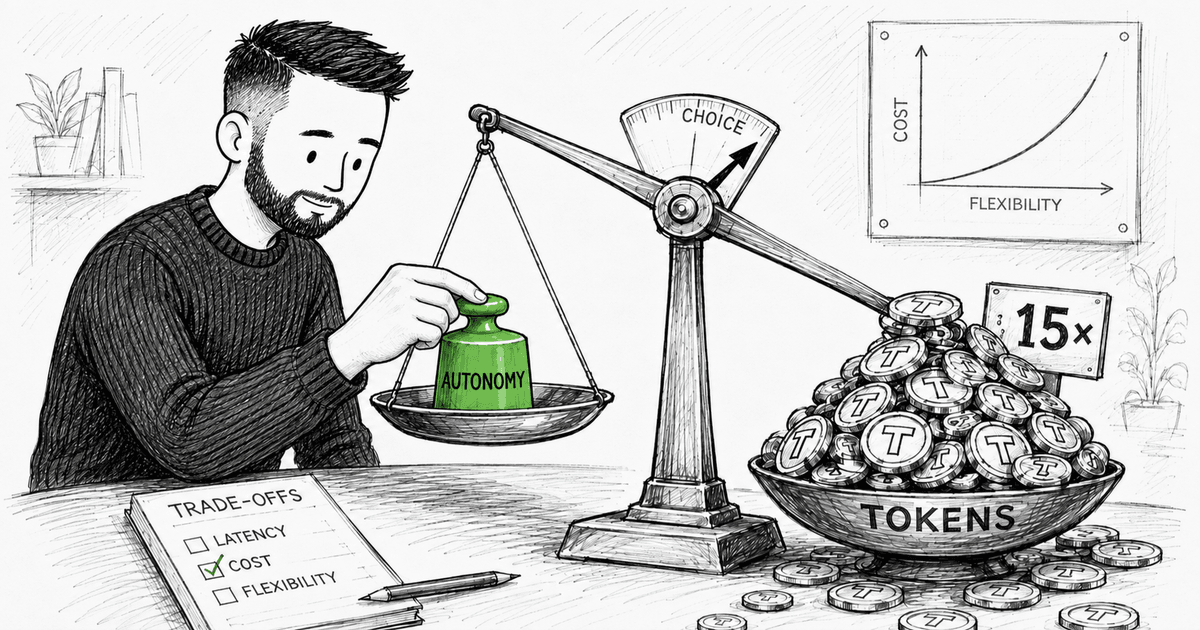
A story made the rounds: someone put an agent on a schedule to keep checking their environment, it got stuck in a loop one night, and instead of a couple of hours it burned through a fortune in tokens by morning. The lesson isn't "watch your usage." It's that cost is a design constraint, and most agent setups treat it as a footnote.
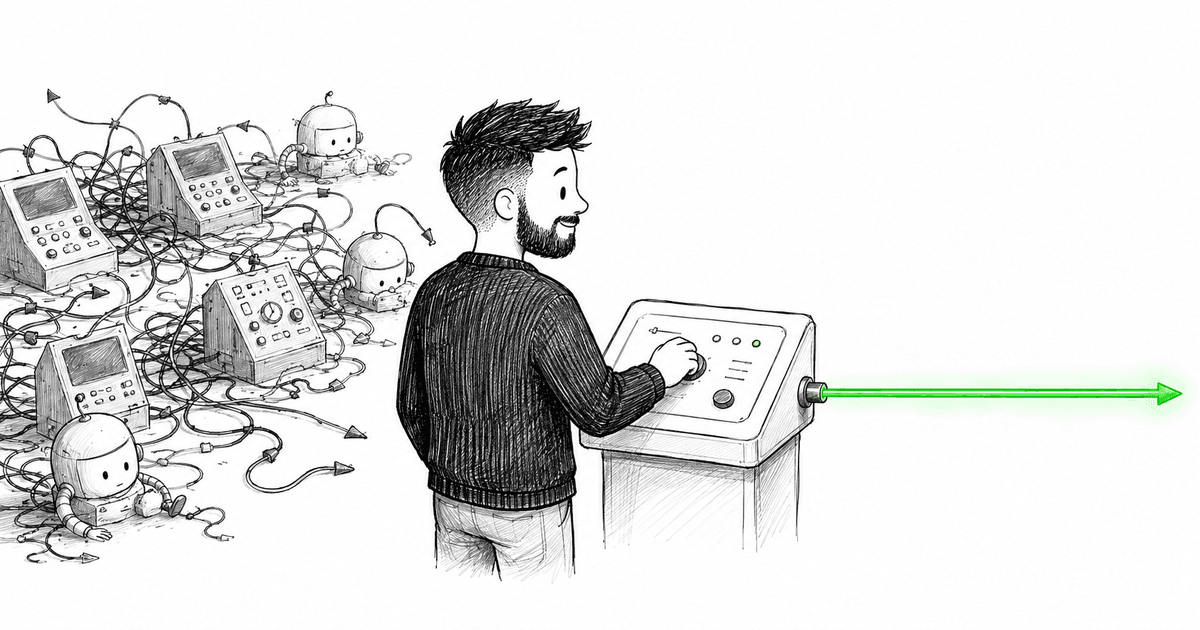
Open almost any "how I use AI" post and you'll find an orchestra: a planner agent, a coder agent, a reviewer agent, a tester agent, all pinging each other. It looks impressive. It's also the most expensive, most fragile way to get worse results than one agent you actually taught to do the job.
Every performance guide tells you to lazy-load. Almost none tell you where to stop. Split on your file tree and you trade one big bundle for a hundred tiny chunks and a waterfall of spinners. The real question isn't how to split — it's finding the seams in the user's journey and cutting there.
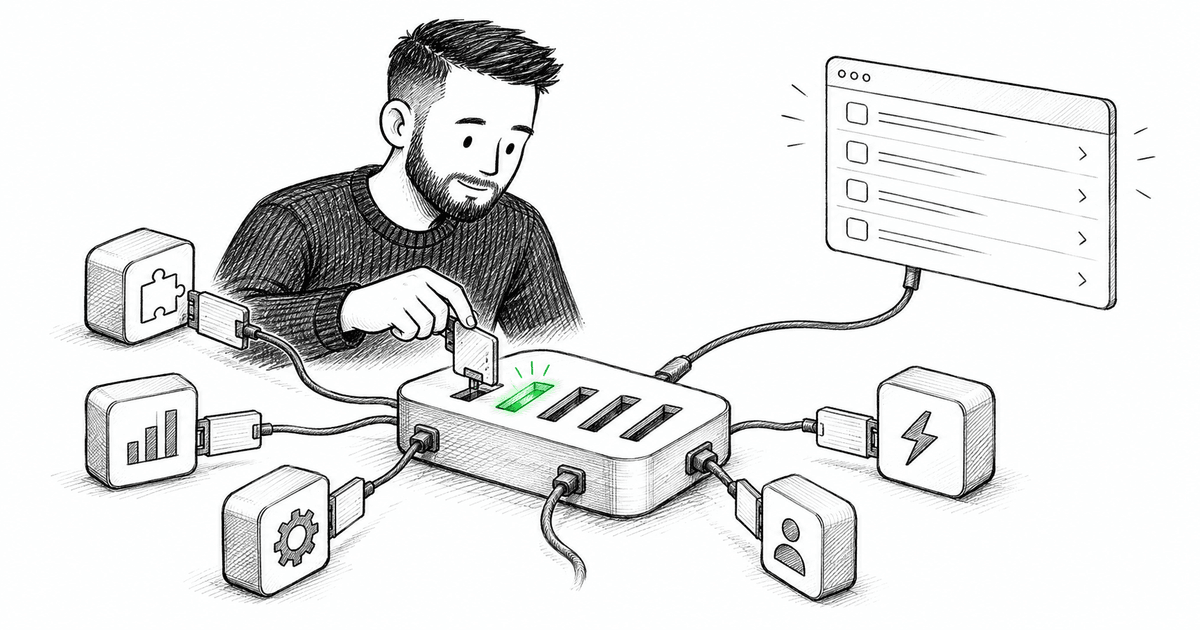
Cmd+K looks like a fuzzy-search modal you bolt on at the end. Build it that way and it immediately drifts out of sync with the buttons and menus it duplicates. The real thing is a command registry: one typed source of truth for everything the app can do, feeding the palette, the shortcuts, and the menus at once.
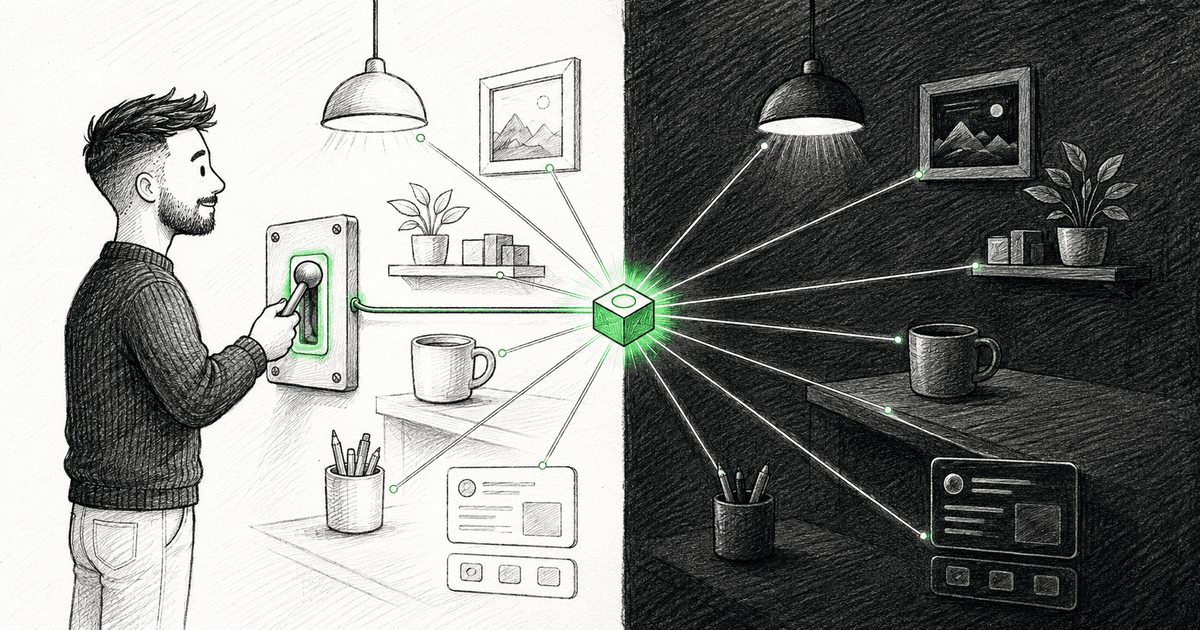
Dark mode looks like a class you toggle. Then you meet the flash of the wrong theme on load, colors that drift because every component hardcodes its own, and a theme context that re-renders the whole app. Theming done right is tokens, one switch point, and a boundary — and it barely touches React at all.
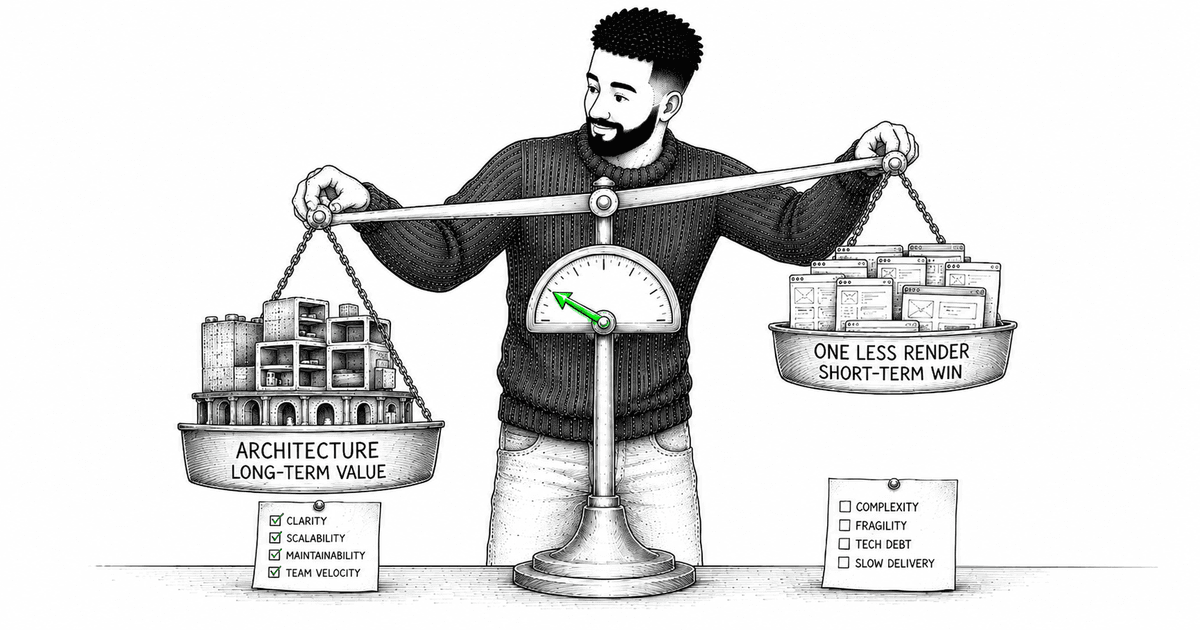
There's a particular panic I keep running into: a component re-rendered, someone saw it in the profiler, and now they're tearing the architecture apart to stop it. But rendering isn't React's flaw — it's the whole idea. The word you want is optimize, not minimize, and the difference decides whether your app stays maintainable.
Most analytics code is a scatter of track('button_click') calls with drifting names, mystery payloads, and three vendor SDKs called inline. Analytics is a cross-cutting concern, and it belongs in a layer with a typed event catalog — not smeared through your components. Here's how I structure it.
Feature flags decouple deploy from release, and that's genuinely powerful. But every flag is a fork in your code, forks multiply, and the ones nobody deletes quietly become the most dangerous debt in the codebase. The architecture isn't the flag — it's how you evaluate, type, and eventually kill it.
An event bus feels like the cure for prop drilling and tangled dependencies — anything can talk to anything, and nothing is wired together. That's exactly the problem. It doesn't remove the coupling, it hides it. Here's where a bus genuinely helps and where it quietly turns your app into action-at-a-distance.
isLoading, isError, isSuccess, isEditing — five booleans give you thirty-two combinations, and most of them are impossible states your code still has to survive. A state machine makes the impossible ones unrepresentable. Here's when to hand-roll one and when to reach for XState.
The instinct is to snapshot your whole state on every change and step backward through the copies. It works until it doesn't. A history of reversible commands scales further, describes what actually changed, and survives contact with a server. Here's how I build undo/redo that doesn't fall apart.
Optimistic UI is a small lie: you show the result before the server confirms it. Done right, the app feels instant. Done wrong, the UI quietly tells the user something that never happened. The difference is entirely in how you roll back.
The same customer shows up in a list, a detail page, and a header badge — three copies of one truth you don't own. Edit one and the others go stale. Here's when to normalize server data into one source of truth, when the query cache is enough, and how to invalidate without nuking everything.
localStorage looks like a global variable that survives a refresh. That framing is the bug. Treat it as a persistence layer that mirrors your state — not as the state itself — and the hydration mismatches, stale tabs, and schema breakages mostly disappear.
A shared UI kit does not fail because the button component is hard to write. It fails when five applications are afraid to upgrade it. Versioning, contract tests, release channels, and migration paths are what turn a component library from a dependency into a product people can trust.
Writing the new version of a shared component is the easy 10%. The other 90% is the hundred call sites that already depend on the old one — and the fear of touching them. Here's how I change a component everyone uses without a month-long rewrite that breaks the day it lands.
The most reusable UI code I write renders nothing at all. Headless components, render props, and hooks-as-API are three names for one idea: separate what a component does from how it looks — and hand over the behavior without a single opinion about the markup.
The moment a component grows past a handful of props, you're not writing a component anymore — you're designing an API. Compound components are how you keep that API flexible without drowning it in configuration props.
The pattern that taught a generation to split 'smart' from 'dumb' components got quietly declared obsolete when hooks arrived. It wasn't. The folder convention died. The idea underneath it is more useful now than ever — including in Server Components.
Split a component too early and you get a maze of tiny files. Split too late and you get a 600-line monster. The real question isn't size — it's who owns which dependency, and whether the component reaches for it or is handed it.
You can draw whatever folder diagram you like. The honest picture of your app is which module imports which — the direction of the arrows. Get that wrong and no folder structure will save you.
A barrel file makes imports look beautiful and can quietly drag half your app into a bundle that only needed one function. Here's what index.ts actually does, when it earns its place, and when it's a trap wearing a clean interface.
Every codebase grows a shared/ folder, and given enough time every shared/ folder becomes a junk drawer. Not because the team got lazy — because the folder was never given a rule. Here's why it rots, and how to keep it boring.

Most engineers treat the Figma file as a picture to reproduce. That framing is why so many handoffs go badly. A good design isn't a picture — it's the first draft of your component architecture, and the decisions that decide whether your codebase stays sane are made before a single line of React is written.
FSD is one of the best frontend methodologies out there. Used without thinking, it turns a complex component into a scavenger hunt across eight folders. Here's what I learned.
Server rendering isn't a performance checkbox — it collapses the wall between frontend and backend into one framework. Here's what SSR really buys you, why the client/server line stops being where you think it is, and where TanStack Start fits next to Next.js.
Auth looks like a login form and turns out to be an architecture decision. Where do tokens live, who guards a route, what happens when the session dies mid-request? Here's why I buy auth instead of building it, and the parts that stay yours no matter what you buy.
Append-only markdown memory works great — until it doesn't. After watching the system degrade in production, our team redesigned it from scratch with strict principles: small, high-signal, controlled, and self-maintaining.
A module I was told not to over-engineer grew into an entire application. Most of what let it survive was boring — and one of the most boring rules was never mutating state in place. Here's how immutability actually works in React, when I reach for Immer, and why I skip Immutable.js.
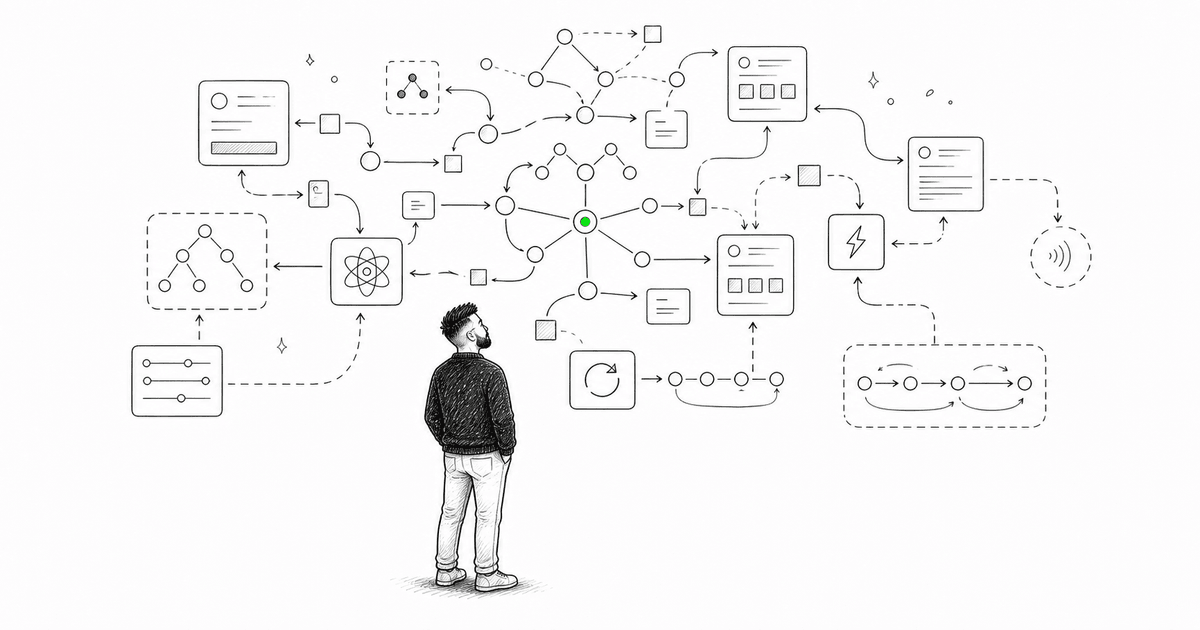
Most React state doesn't need a library. Then one workflow grows into drafts, derived values, undo, optimistic steps, and cross-component coordination. This is where I reach for Reatom instead of turning TanStack Query into a client-state store.
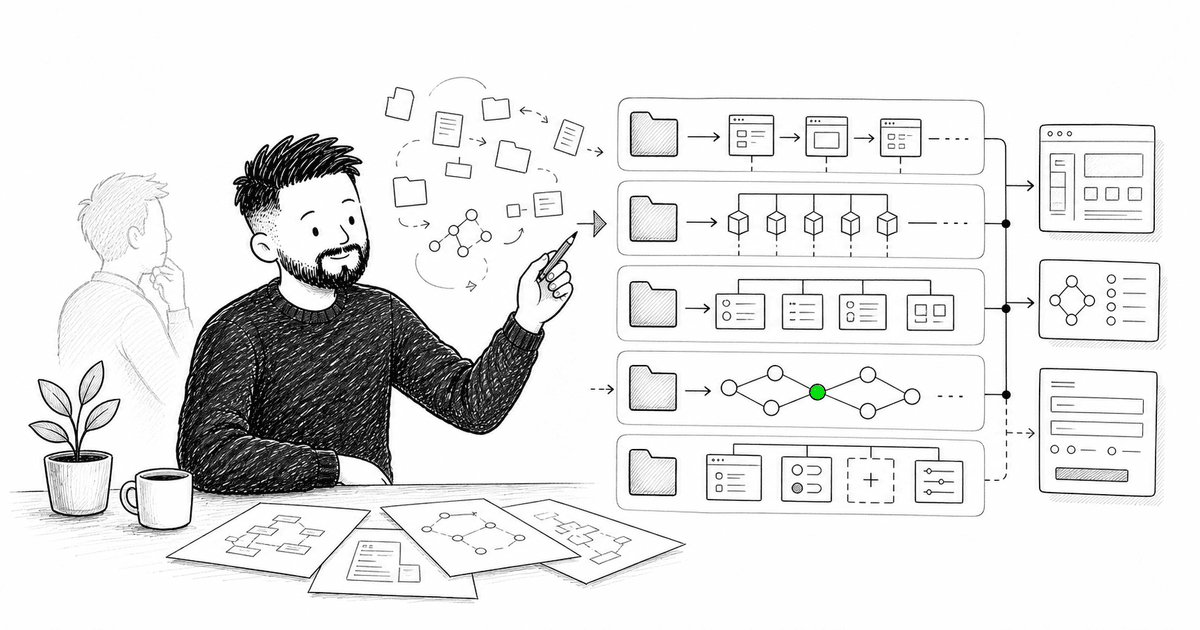
Flat folders are fine until every feature starts touching routes, queries, forms, permissions, and UI state. Here's the React structure I use when a TanStack app grows past the simple stage without turning FSD into folder theater.
How structured documentation dramatically improves AI-generated code quality by giving agents the context they need.
How to build component libraries that teams actually want to use.
Patterns for managing complex form state, validation, and user experience.
How to structure and manage large-scale monorepo projects effectively.